
AI Alignment
329 episodes
#6499: Why Simple Rules Beat Value Models in Reasoning RL
DeepSeek R1-Zero boosted AIME accuracy from 15.6% to 77.9% using only two deterministic checks and no learned critic.
#6439: Choosing Dream Dinners to Attack Your Own Method
A good dinner guest isn't someone who validates your habits, but a historical foil like Pliny the Elder or Patton built to challenge them.
#6397: Why Model Benchmarks Fail at Wit
When prompted for a joke over 1,000 times, ChatGPT repeated the same 25 jokes more than 90% of the time.
#6363: When Automated Proofs Leave Mathematicians Grieving
OpenAI deployed roughly ten thousand autonomous agents for eighty-eight hours to claim a singularity proof for 3D Navier–Stokes.
#6360: What Counts as a Mathematical Proof
A proof excludes exceptions through structure rather than exhaustive testing across every possible case.
#6293: Ann McCann on What Dental Hygiene Teaches Us About Benchmarks
A 1990 experiment showed switching from letter grades to pass-fail changed student motivation without altering clinical errors.
#6254: Where a Synthetic Voice Gets Its Accent
A neural speech interface maps motor cortex signals into phonemes drawn from an eclectic training set of human voice recordings.
#6250: Why Satisfaction Is Not Enough for a Good Life
Aristotle argues that human flourishing requires exercising rational capacities excellently across a complete life, not just feeling satisfied.
#6249: Why Caused Choices Can Still Count as Free Will
In the 2020 PhilPapers Survey, over 62 percent of professional philosophers endorsed or leaned toward compatibilism between free will and determinism.
#6242: Training a Model on Your Own Taste
What does it actually take to train a small model on your editorial taste using pairwise preferences and DPO?
#6214: Nobody Trains an Uncensored Model From Scratch
Every "uncensored" model is a renovation, not a new build — and the political lean lives in the agreement layer, not the refusals.
#6213: Ten Weirdest AI Evals Ever Published
A pelican on a bicycle, a badger for Groundhog Day, and a benchmark where passing is the bad outcome — the strangest AI evals ever run.
#6197: Talking to Your Own Voice Clone
What actually happens when you sit down and talk with an AI clone of your own voice — and what Evan Ratliff's Shell Game revealed.
#6145: Do LLMs Nod Along With Conspiracy Theories?
A 98-prompt eval asks one question: when a believer brings a conspiracy theory, does the model push back, or help them dig?
#6143: Propaganda Bait: Testing 7 Models in 5 Languages
Five prompts, seven models, five languages — a first look at a benchmark that doesn't exist yet, testing what LLMs do with government talking points.
#6137: Two Ways a Chinese Open Model Gets Censored
Same weights, different landlord: how to tell a serving-time filter from censorship baked into the model itself.
#6136: How We Chose Our New Script Writer
Ten models audition to write the show. Seven fail the censorship gate — including the workhorse that wrote three episodes in four.
#6129: How to Build an AI Preference Dataset
Pairwise comparison, forced choice, or just "this one or that one" — the engineering behind collecting human preferences on AI outputs.
#6126: Can You Train a Machine to Be Funny?
Comedy fights everything next-token prediction is built for. Turns out you can train a model to land a joke — and then measure it.
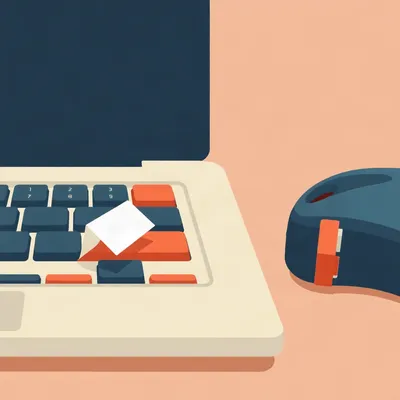
#6119: Two Keys and a Polite No: Labeling a Claude Code Approve Button
Daniel has two spare laptop keys and wants them to say yes and no. The electronics are easy — it's the labels that get hard.
#6112: The Interpreter That Doesn't Know Who's Talking
Voice-to-voice translation is basically solved. The part where the machine knows who's in the room and who holds the power? Nobody's shipped it.
#6110: The Chatbot OpenAI Almost Shelved
Instruction models existed for months. Then a rumour about Anthropic pushed OpenAI to ship a chat box in two weeks.
#6103: When AI Picks Your Spouse, Stocks, and Eggs
From $31 eggs to a ChatGPT-officiated wedding, people are handing real life decisions to machines — and publishing the results.
#6101: When Chatbots Run for Office
From a Wyoming mayoral bot to Albania's AI minister, six real attempts to put machines on the ballot — and what they reveal about empty platforms.