
Hallucinations
306 episodes · Page 9 of 13
#2006: How Do You Measure an LLM's "Soul"?
Traditional benchmarks can't measure tone or empathy. Here's how to evaluate if an AI model truly "gets it right."
#2005: Beyond Vibes: The Hard Science of LLM Evaluation
Running the same LLM on different GPUs can produce different results. Here’s why that happens and how to test for it.
#1994: Why Can't AI Admit When It's Guessing?
Enterprise AI now auto-filters low-confidence claims, but do these self-reported scores actually mean anything?
#1986: Desk Robots: Privacy, Power, or Annoyance?
These AI companions sit on your desk, watching your posture and listening in—so how do they protect your privacy while actually being useful?
#1985: AI Tutors vs. Human Error: Who Do You Trust?
AI gets flak for hallucinations, but humans misremember 40% of facts. Why the double standard?
#1961: Weaponizing Your Weirdness in an AI World
As AI homogenizes the web, contrarian thinking becomes a scarce asset. Here’s how to weaponize your weirdness for a competitive edge.
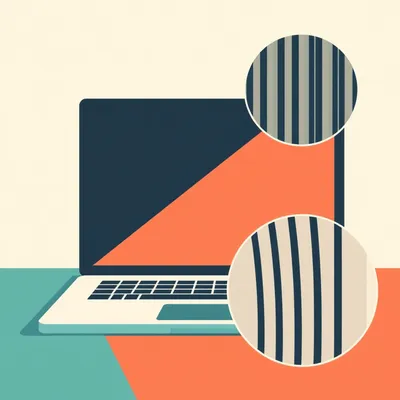
#1960: The Microscopic Venetian Blinds in Your Screen
A coffee shop glance reveals a black slab, not your data. Discover the microscopic Venetian blinds making it possible.
#1959: How Constrained AI Models Handle the Unexpected
Your AI assistant promised to only use your documents. Instead, it invented a case law that doesn't exist. Here's why.
#1932: How Do You QA a Probabilistic System?
LLMs break traditional testing. Here’s the 3-pillar toolkit teams use to catch hallucinations and garbage outputs at scale.
#1929: From Vibe Checks to Model Metrics
We stopped "vibe-checking" our AI scripts and built a science fair for models. Here's how we grade them.
#1914: Google Invented RAG's Secret Sauce
Before LLMs, Google solved the "hallucination" problem with a two-stage trick that's making a huge comeback.
#1904: The Hidden Math Behind Your Blocky Photos
Why are blocky sky artifacts still haunting your photos in 2026? We break down the math behind JPEG, WebP, AVIF, and the new JPEG XL.
#1893: AI as a Strategic Adversary for Startups
Can AI stress-test your startup idea before investors do? We explore using AI as a strategic adversary to find blind spots.
#1856: Two AIs Chatting Forever: Why They Go Crazy
What happens when two ChatGPT instances talk forever? They hit a politeness loop, forget their purpose, and spiral into gibberish.
#1852: The BCI Inflection Point: Trade-offs Between Implants and EEG
We trace BCIs from 1970s EEG caps to today’s high-bandwidth implants, comparing Neuralink and Synchron’s invasive vs. minimally invasive approaches.
#1851: AI Toasters and Poetic Gym Coaches: Why We’re Drowning in Useless AI
From smart toasters that need Wi-Fi to email rewriters that sound like corporate robots, here are the most baffling AI features we’ve seen.
#1831: The 79% AI Coder: Reasoning vs. Memorization
AI models now score 79% on coding benchmarks, but a 40-point drop on harder tests reveals the truth.
#1819: Claude's 55-Day Personality Transplant
Anthropic leaked 55 days of system prompt updates. See exactly how they rewired Claude's personality, safety rules, and self-awareness.
#1808: The Architecture That Made AI Voices Run on a Raspberry Pi
How a model the size of a tweet outperforms billion-dollar giants in the race for perfect AI speech.
#1806: Why Mac Minis Are Eating AI's Hardware Race
Apple Silicon's unified memory is crushing traditional GPUs for local LLMs. Here's why the M4 Mac Mini is the new king of affordable AI hardware.
#1762: Testing AI Truthfulness: Beyond Vibes
Stop trusting confident AI. We explore the formal science of testing LLMs for hallucinations and knowledge cutoffs.
#1738: Hyperstition Engines: When AI Writes Reality
LLMs aren't just predicting the future; they're generating the narratives that force it into existence.
#1735: The Agentic Stone Age: A Retrospective
We revisit the chaotic rise of BabyAGI and AutoGPT, exploring why their promise of total autonomy led to spectacular failure.
#1731: Why Deep Research Agents Are Being Forgotten
Specialized research agents outperform general orchestrators by 40-60% on verification tasks, yet developer hype is fading. Here's why.