
Local AI
394 episodes · Page 10 of 17
#3406: LoRA Isn’t Just for Image Generation
LoRA lets you fine-tune an LLM’s behavior with a 50MB file. Here’s how it works and why it matters.
#3322: Desk Pets: Local AI on Your Desktop
Are desk pets useful tools or expensive Tamagotchis? We break down the local AI, privacy tradeoffs, and psychology behind these devices.
#3283: Fine-Tuning DeepSeek for One Podcast
Can a purpose-specific fine-tune fix a model's stubborn writing tics? We explore the practical engineering behind it.
#3218: Building Your Own Cloud in 2026
The software and hardware for a DIY private cloud have never been more feasible. Here's how to pick the right pieces.
#3058: How to Get 15 Hours of Light From Your UPS
Turn your UPS into an emergency light source with the right LED bulb, NUT, and Home Assistant automation.
#3020: How Chatterbox Locks Your Voice Clone Across Thousands of Generations
Why most single-shot TTS models drift over time—and how Chatterbox's cached embedding approach solves it.
#2940: Distrobox: Linux Containers for Humans, Not Servers
Run any distro's apps on any Linux host—no VM, no dual-boot, no dependency hell.
#2911: Building a $180 Privacy-First AI Wearable
How Omi's $99 dev kit lets you build a local-first voice productivity system that watches your screen.
#2900: From Piggy Tier to Production: Making Kids Animation in 2026
Breaking down what it takes to make a YouTube Kids cartoon — and where AI actually helps.
#2754: Why Your Dictation Setup Might Be Wrong
Modern ASR is shockingly robust. The biggest predictor of accuracy? How well your audio matches its training data.
#2693: When AI Ignores Your Style Guide
Why your AI ignores formatting instructions and how to fix it with pipeline architecture, not model swaps.

#2668: When a Flamethrower Is Overkill
Tesseract, EasyOCR, or a cloud vision model? How to build a fast, reliable label scanner for real-world conditions.
#2597: Voice Control for Renters: $25 Per Room, No Wall Damage
Distributed voice control on a budget with wake words, centralized processing, and zero wall damage — perfect for rentals.
#2591: Decoupling Script from Voice
How dynamic voice replacement could let listeners choose who narrates each host's lines.
#2567: Beyond Pixels: Controlling Apps Without Vision
How MCP agents can use accessibility APIs and COM to control Windows and macOS apps at the protocol level.
#2545: Visual AI Pipelines: Beyond Python Glue Code
From ComfyUI to Dify — a tour of visual tools for building modular AI workflows without writing glue code.
#2536: Self-Hosted Zapier Alternatives in 2026
n8n, Huginn, and Dagu compared for personal automation on your own hardware.
#2517: How Unsloth Makes LLM Fine-Tuning 2x Faster
Unsloth cuts memory usage by 50-70% and speeds up training 2.2x for models like Llama 3 and Mistral.
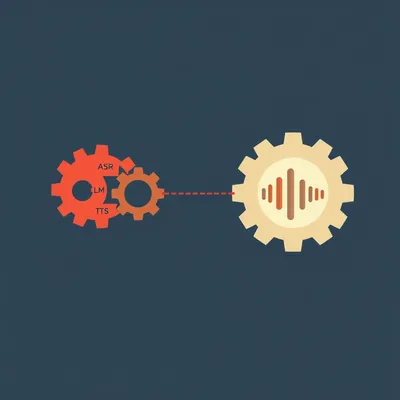
#2512: How Speech-to-Speech Models Eliminate the Robot Voice
Why AI voice agents sound robotic, and how natively integrated speech-to-speech models fix it.
#2495: How to Bake Personality Into an LLM in 15 Minutes
Fine-tune a model's personality with ~300 examples and a consumer GPU. SFT + DPO explained.
#2488: Hybrid Pipelines for Entity Resolution
Classic NLP pipelines vs. lightweight LLMs for handling Hezbollah’s half-dozen spellings.
#2486: Why Noise Reduction Can Ruin Transcription Accuracy
Cleaning audio before transcription can increase errors by up to 46%. Here's the right approach for your voice app.
#2483: Substitution Anonymization: Privacy Without Utility Loss
How to generate realistic synthetic voice notes and calendar data with zero PII exposure risk.
#2470: Where Intelligence Should Live in Your Pipeline
When should you fine-tune a tiny model for prompt enhancement instead of prompting a large one? The answer depends on latency, precision, and domain.